A collection of things I've built

  • Power swings in LLM training

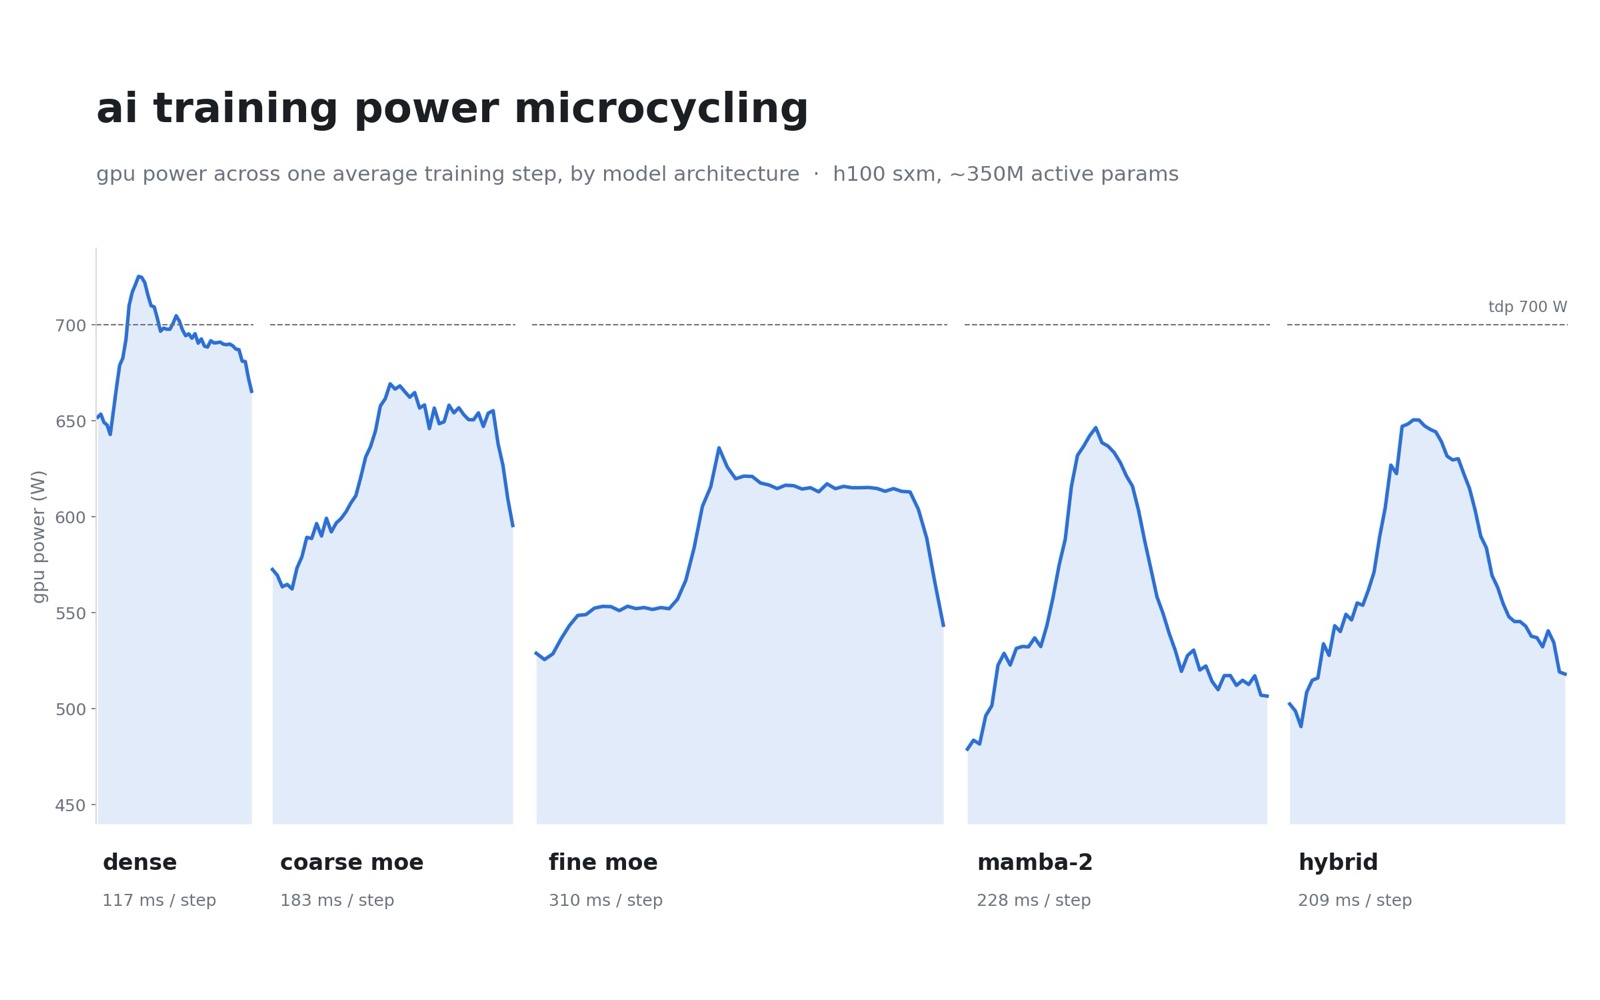
    A study of how GPU power swings and usage patterns differ across model architectures, motivated by the spike-y nature of AI power demand and its effect on the grid and surrounding communities. I compared training power usage for dense, mixture-of-experts, Mamba-2, and hybrid models.

    GitHub
    Power swings in LLM training
  • LLM inference engine

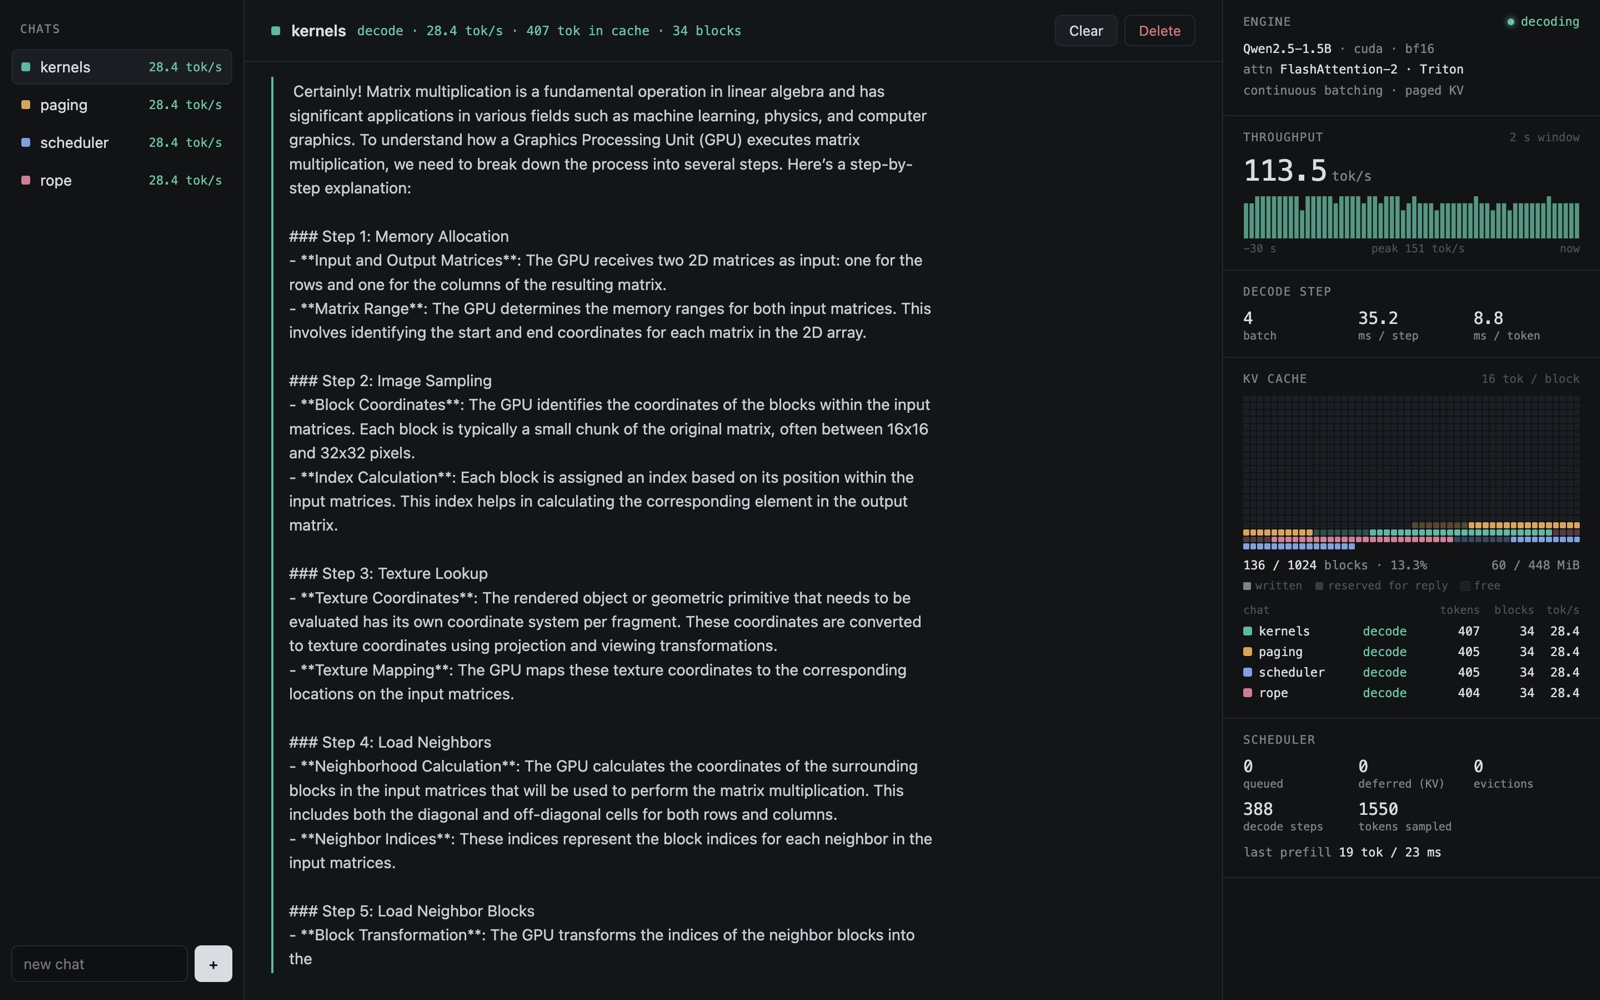
    An LLM serving engine that runs Qwen2.5-1.5B on my own implementation of the model, with a paged KV cache, continuous batching, and a FlashAttention-2 kernel written in Triton. It matches Hugging Face throughput at low concurrency and scales about 10x from 1 to 16 concurrent chats.

    GitHub
    LLM inference engine
  • GPT from scratch

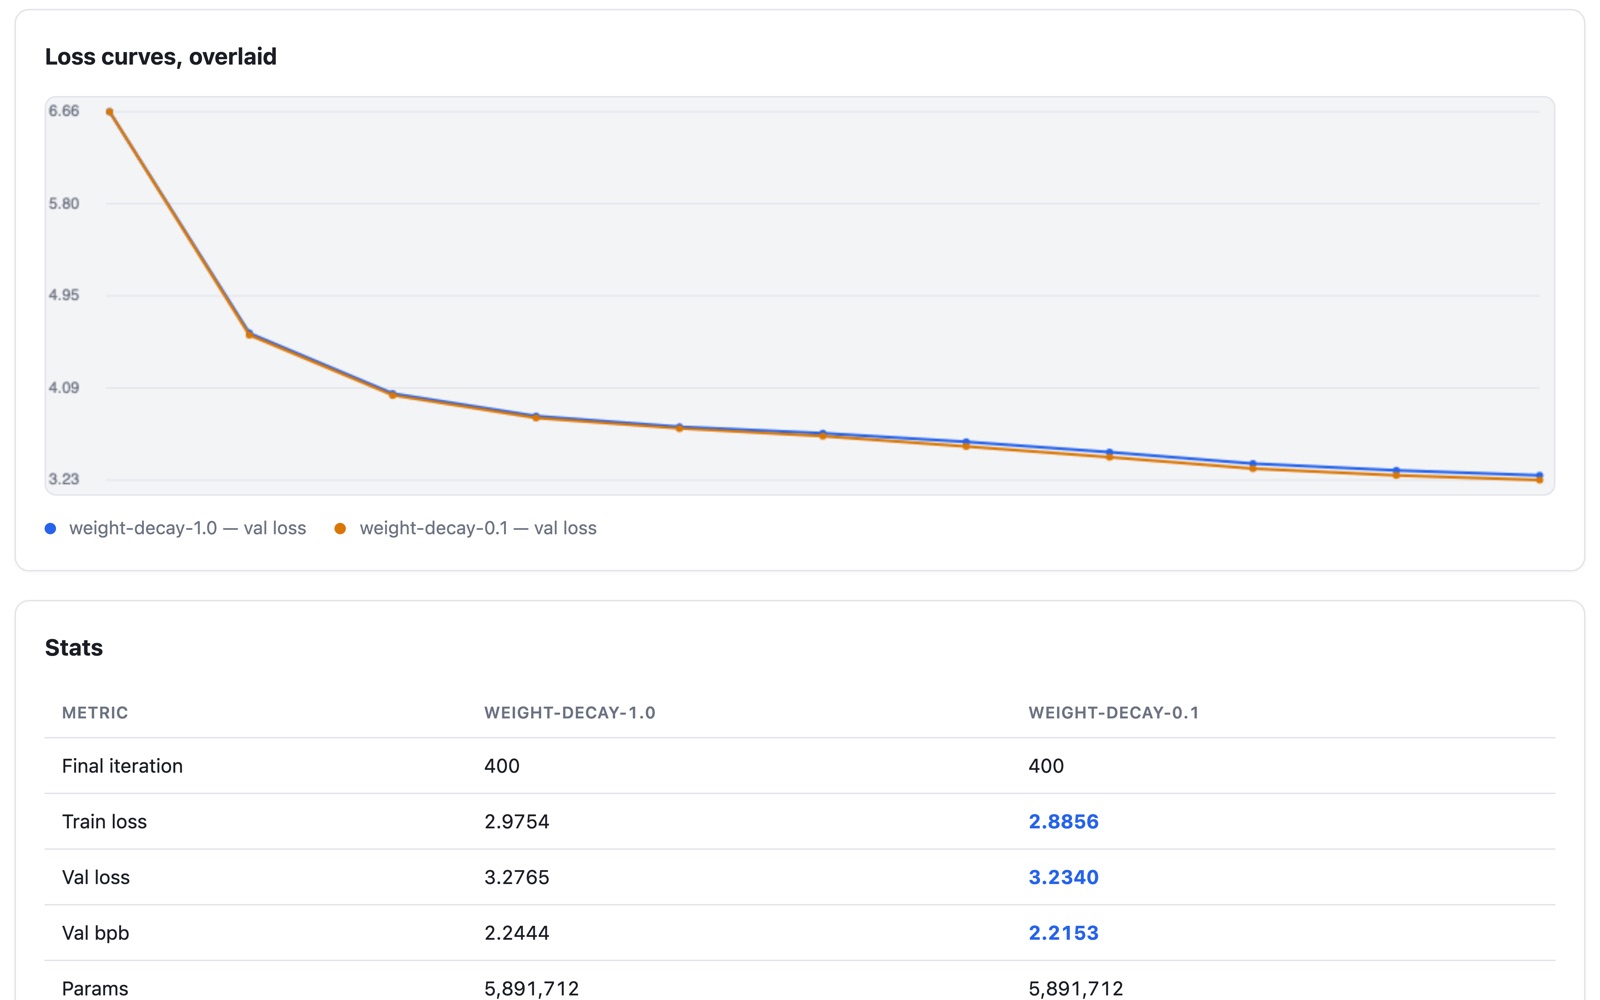
    A decoder-only GPT I built from scratch and trained on Tiny Shakespeare, then used to run 8 controlled experiments on the pieces of modern LLMs (RoPE, RMSNorm, SwiGLU, BPE, and more). Includes a web UI to train, compare, and chat with models.

    GitHub
    GPT from scratch

more to come --